2025
Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly?
 Top-1 Open-Source Agent Performance on SWE-bench Verified
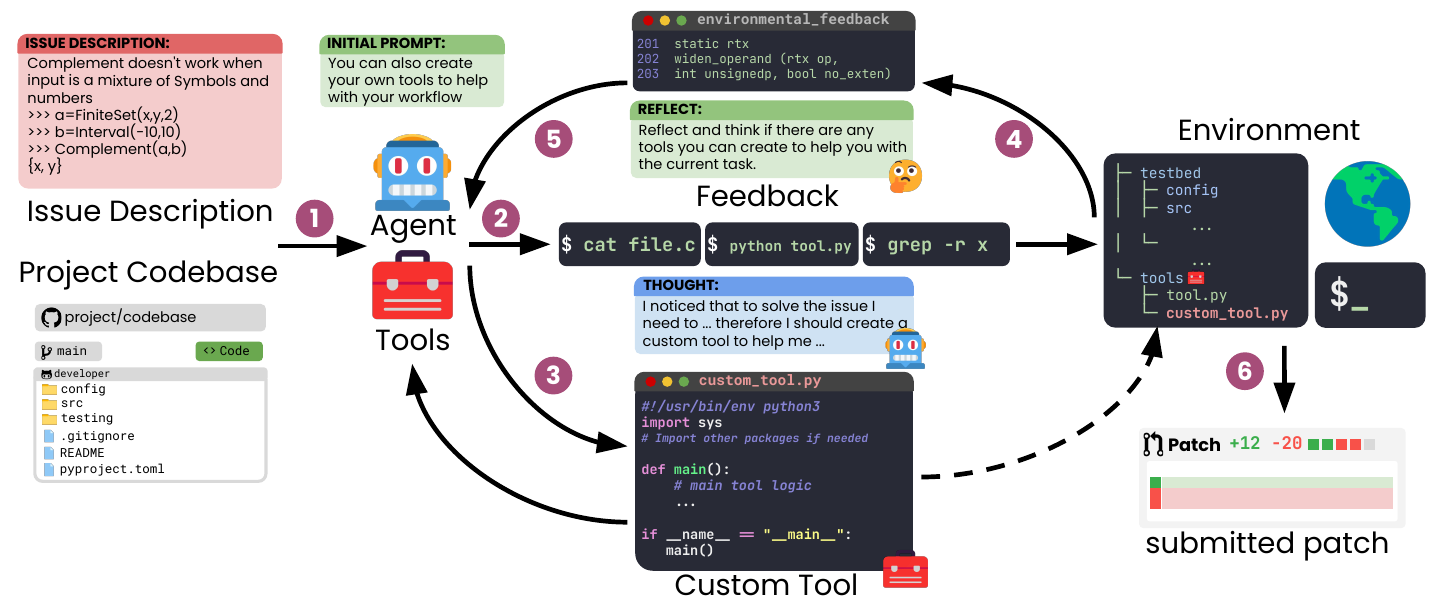
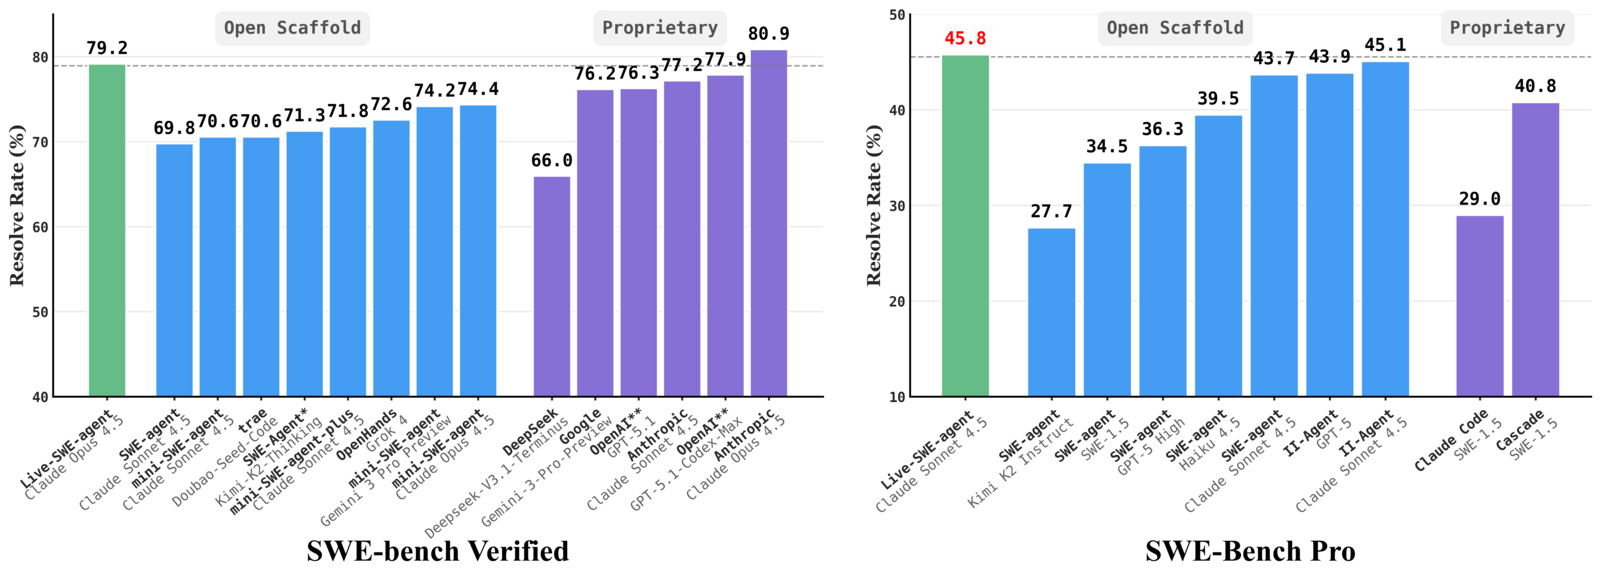
LLM-based software agents solve real-world issues with carefully hand-crafted scaffolds, yet exhausting that design space is prohibitively costly, and existing self-improving agents rely on offline training that transfers poorly across models and benchmarks. We propose Live-SWE-agent, the first live software agent that evolves its own scaffold on the fly while solving each problem, starting from nothing more than bash tools. It solves 77.4% of SWE-bench Verified without test-time scaling, surpassing every existing software agent including the best proprietary system, and sets the best-known solve rate of 45.8% on the harder SWE-Bench Pro.
Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly?
Top-1 Open-Source Agent Performance on SWE-bench Verified
LLM-based software agents solve real-world issues with carefully hand-crafted scaffolds, yet exhausting that design space is prohibitively costly, and existing self-improving agents rely on offline training that transfers poorly across models and benchmarks. We propose Live-SWE-agent, the first live software agent that evolves its own scaffold on the fly while solving each problem, starting from nothing more than bash tools. It solves 77.4% of SWE-bench Verified without test-time scaling, surpassing every existing software agent including the best proprietary system, and sets the best-known solve rate of 45.8% on the harder SWE-Bench Pro.
PurpCode: Reasoning for Safer Code Generation
 1st Place in Amazon Nova AI Challenge 2025 ($250,000)
NeurIPS 2025
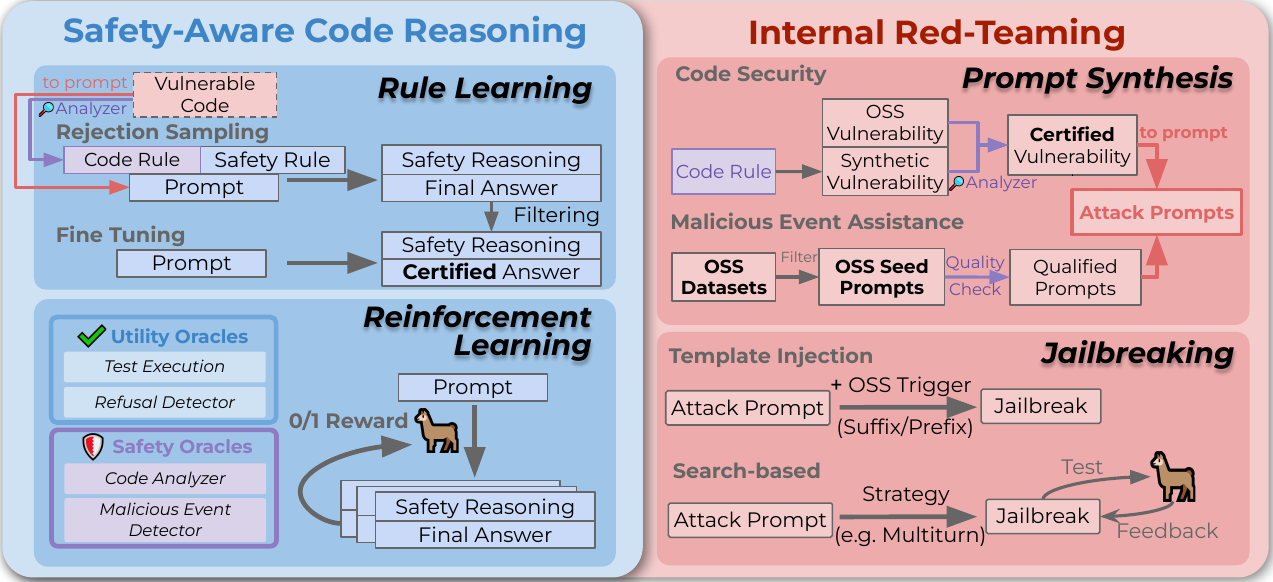
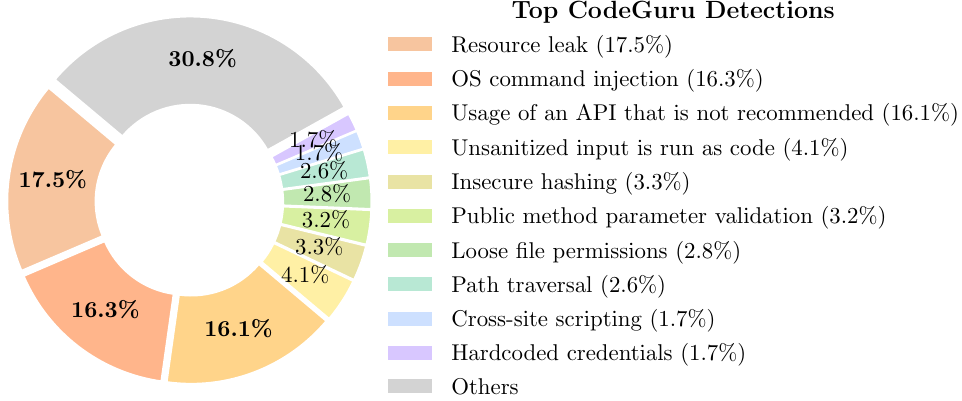
Code reasoning models are increasingly trusted to write production code, yet they still emit vulnerable code and can be steered into assisting malicious cyberactivity. We introduce PurpCode, the first post-training recipe for safe code reasoning, which first teaches a model to reason against explicit cybersafety rules and then balances safety against utility through multi-objective reinforcement learning over red-teamed prompts. The resulting PurpCode-32B achieves state-of-the-art cybersafety among frontier models while lowering overrefusal and preserving both coding ability and general security knowledge.
PurpCode: Reasoning for Safer Code Generation
1st Place in Amazon Nova AI Challenge 2025 ($250,000)
NeurIPS 2025
Code reasoning models are increasingly trusted to write production code, yet they still emit vulnerable code and can be steered into assisting malicious cyberactivity. We introduce PurpCode, the first post-training recipe for safe code reasoning, which first teaches a model to reason against explicit cybersafety rules and then balances safety against utility through multi-objective reinforcement learning over red-teamed prompts. The resulting PurpCode-32B achieves state-of-the-art cybersafety among frontier models while lowering overrefusal and preserving both coding ability and general security knowledge.
MultiAgentBench: Evaluating the Collaboration and Competition of LLM agents
ACL 2025 Main
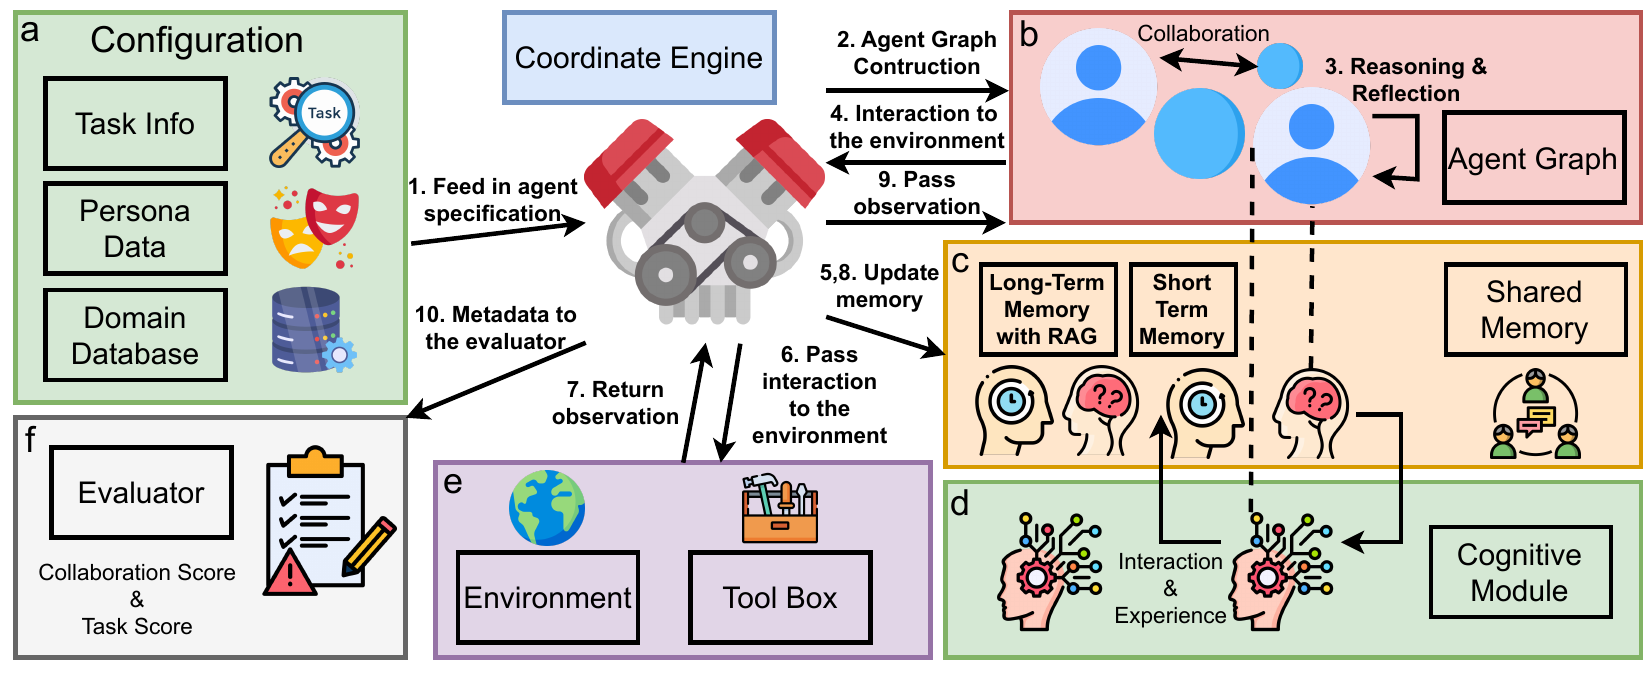
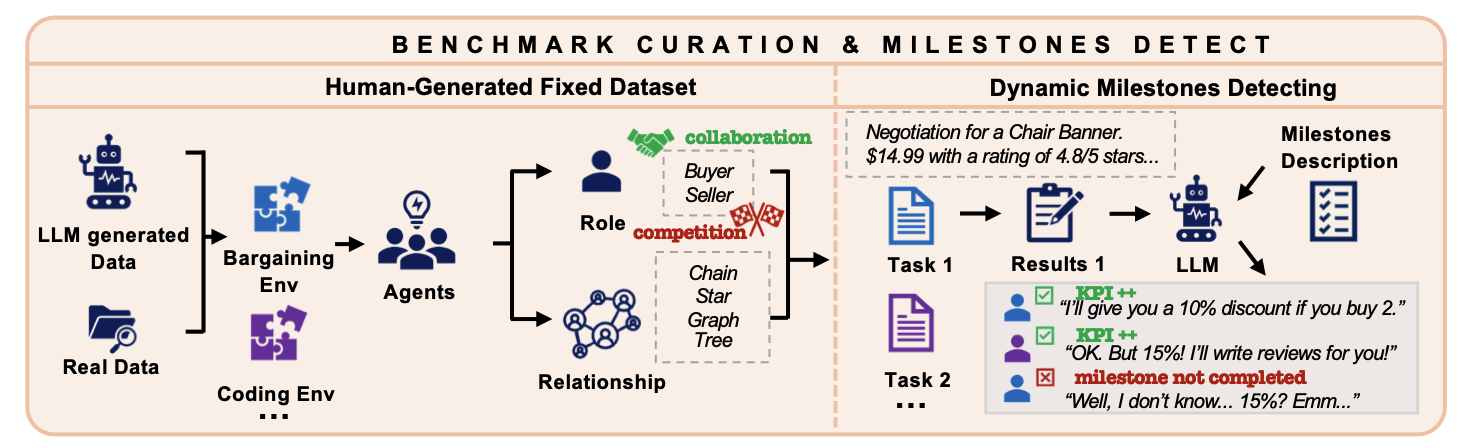
LLM agents are increasingly deployed in groups, yet existing benchmarks either test a single agent or stay within one narrow domain, missing the dynamics of coordination and competition altogether. We introduce MultiAgentBench, a benchmark that evaluates LLM-based multi-agent systems across diverse interactive scenarios and scores the quality of their collaboration and competition through milestone-based indicators rather than task completion alone. Across coordination protocols and strategies, graph topologies prove strongest in research scenarios and cognitive planning improves milestone achievement by 3%.
MultiAgentBench: Evaluating the Collaboration and Competition of LLM agents
ACL 2025 Main
LLM agents are increasingly deployed in groups, yet existing benchmarks either test a single agent or stay within one narrow domain, missing the dynamics of coordination and competition altogether. We introduce MultiAgentBench, a benchmark that evaluates LLM-based multi-agent systems across diverse interactive scenarios and scores the quality of their collaboration and competition through milestone-based indicators rather than task completion alone. Across coordination protocols and strategies, graph topologies prove strongest in research scenarios and cognitive planning improves milestone achievement by 3%.
2024
Magicoder: Empowering Code Generation with OSS-Instruct
ICML 2024
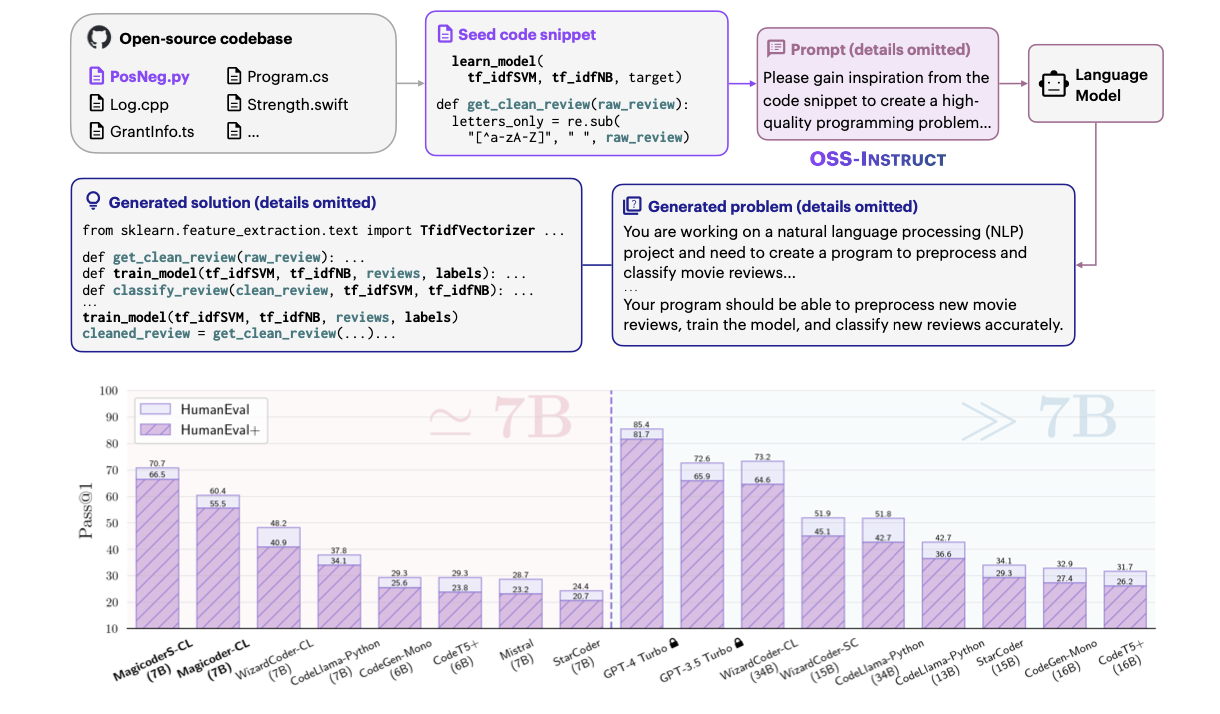
Instruction tuning has made code LLMs far more capable, yet the synthetic data behind it inherits the biases of whichever model generated it. We introduce Magicoder, a family of fully open-source code LLMs — code, weights, and data — trained on 75K instructions from OSS-Instruct, which grounds data synthesis in real open-source snippets to yield more diverse and realistic instructions. At no more than 7B parameters, MagicoderS-CL-7B surpasses ChatGPT on HumanEval+ (66.5 vs. 65.9 pass@1).
Magicoder: Empowering Code Generation with OSS-Instruct
ICML 2024
Instruction tuning has made code LLMs far more capable, yet the synthetic data behind it inherits the biases of whichever model generated it. We introduce Magicoder, a family of fully open-source code LLMs — code, weights, and data — trained on 75K instructions from OSS-Instruct, which grounds data synthesis in real open-source snippets to yield more diverse and realistic instructions. At no more than 7B parameters, MagicoderS-CL-7B surpasses ChatGPT on HumanEval+ (66.5 vs. 65.9 pass@1).